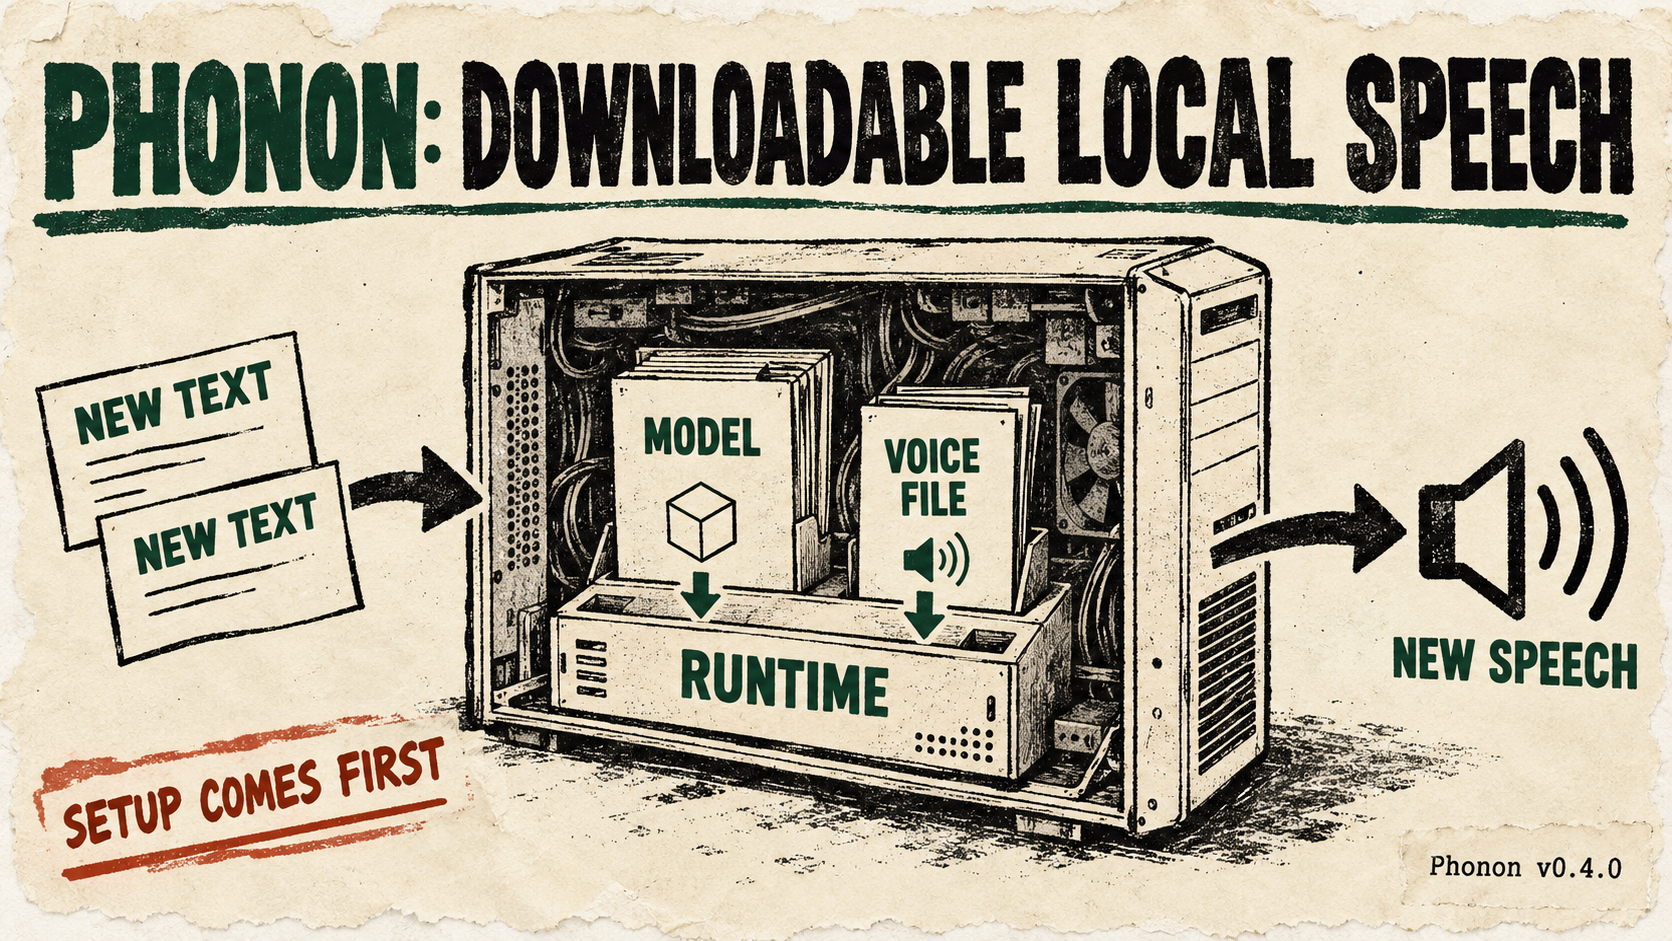
On October 20, Gradium published public Phonon model weights alongside its v0.4.0 speech runtime in gradium-ai/xn-ptts. For an application that needs to say something aloud, the consequential change is access: developers can obtain the speech generator’s parts, keep them on a device and feed it new text.
The April 3 offer already promised offline, CPU-based speech. It described a licensed binary tailored to a voice, language and use case. The public release expands that offer with components developers can assemble themselves. It does not establish that the bespoke service has ended—or that local speech has just been invented.
A voice kit you can keep
The runtime runs the model. A reusable voice embedding conditions how it speaks. New text can use the same local kit again.
New text: “The library closes at six.”
Generated output: Speech can be generated locally from this text.
Download the model, runtime and a ready catalogue voice. For a custom voice, the documented Gradium preparation route uses its hosted service before you download the voice file.
Obtain the assets, then keep them on the device
Plates, top to bottom: voice file, model, runtime.
- Runtime
- The program that runs speech generation.
- Model
- The learned weights used to generate speech.
- Voice embedding
- A reusable conditioning file, not a recording of the next sentence.
Once the required assets are local, repeated synthesis can use fresh text without a speech-service request. This diagram explains the arrangement; it does not run Phonon, play audio or measure speed.
The voice file survives the sentence
Three pieces do different jobs. The runtime is the program; the model supplies learned speech-generation weights; the voice embedding conditions how the generated speech sounds. An app can change its words without preparing that voice again. The checkpoint loader accepts a local model directory, while the synthesizer loads separate voice files. Keeping these assets together is what makes repeated local use practical.
A developer can start with a ready voice from the public catalogue. No custom recording is needed for that route. The freely downloadable 31-million-parameter English model carries an Apache 2.0 license. The release’s larger 40-million-parameter models have a noncommercial license and gated access. “Public weights” is therefore not one permission covering every language and deployment.
We ran the released Linux binary on a CPU with two short English inputs. After the first download, a second run used explicit local model and voice paths and produced a fresh 24 kHz mono WAV. System-call tracing recorded no network calls during that run. This checks a narrow, useful property: generation can work from the downloaded assets. We did not assess intelligibility, compare latency, or test a phone, another language or a custom voice.
Preparing a voice is a different boundary
The documented Gradium custom-voice script sends a recording to its hosted API, then downloads a voice file for later synthesis. That preparation step cannot be described as entirely offline merely because the resulting speech generator can run locally.
There is also a local voice-preparation example in the source. It requires a speaker encoder. The released English model artifact we inspected—the runtime’s pinned checkpoint—does not include that encoder. The distinction matters: code for a local route exists, but that does not make this downloaded checkpoint a complete local voice-preparation kit.
A choice that was previously bespoke
The comparison is broader than Gradium. Kyutai’s Pocket TTS already documented CPU-based local speech in February, including exporting a reusable voice from local audio. Phonon’s release adds an obtainable implementation to that choice; it does not demonstrate better sound, lower cost or compatible voice-file formats.
For a kiosk, local assistant or other application that needs fresh spoken responses, the useful question is now concrete: can this English model and an available voice meet the application’s requirements? Developers can try that without commissioning Gradium’s bespoke binary. The next missing piece to watch is equally concrete: an obtainable, Phonon-compatible package that can prepare a custom voice entirely locally, followed by a test of how well it speaks.